SID AI Releases SID-2 Agentic Search Model With 0.720 NDCG Swarm Mode
SID AI has released SID-2, its second-generation agentic search model, alongside SID-2 Swarm. SID-2 is an agentic search model from SID AI that searches your data, reads results and returns ranked document IDs. It replaces fixed RAG pipelines with a model that decides what to search next.
TL;DR
- Size: Context window is 262k tokens per the report (256k on sid.ai/models).
- Runs on: Hosted API at platform.sid.ai, plus Baseten and SageMaker reference paths. SID’s latency figures assume 1 B200 GPU at 8 concurrent queries.
- Performance: A single agent matches Claude Opus 5.5 on retrieval quality. Swarms beat every model SID tested.
- Best: SID-2 Swarm (12 agents) scores 0.720 NDCG, above GPT-6 Astra at 0.704.
- Worst: SID-2 Low scores 0.556 NDCG, 0.148 below GPT-6 Astra. Astra still leads on California law, SEC filings and FiQA.
- Bottom line: Best: frontier-level retrieval at a fraction of the latency. Worst: no disclosed size, weights or independent evals yet.
What is SID-2 and how does it work?
SID-2 is a small search specialist, not a general chat model. A static pipeline runs rewrite, embed, search and rerank in a fixed order. SID-2 instead searches, reads results, adapts and searches again.
Developers implement the search tools against their own backend. A text_search tool covers keyword search and a search tool covers vector search. The model ends each episode by calling report_helpful_ids with a ranked list. No reindexing or data movement is required, since SID-2 only sees what your tools return.
SID-2 Swarm runs several agents that message each other and fork their context into new agents. Each agent explores a separate slice of the corpus. SID argues search gains more from reading more documents than from reasoning harder about each one.
What are reasoning effort and Metric Steering?
SID-2 offers low, medium and high reasoning effort. Each level was trained as a separate expert, then merged with multi-teacher on-policy distillation. Metric Steering lets users target NDCG, F1 or Recall@k, with k from 1 to 50. On SID’s 506-question validation set, SID-2 at high effort scores 0.14 to 0.22 higher per metric than the base model.
How was SID-2 trained?
Training used 2-stage reinforcement learning. Stage 1 optimizes retrieval quality only. Stage 2 adds a multiplicative latency penalty that applies only to positive rewards. A proposer-solver self-play loop generated hard queries against a frozen SID-1 solver. SID reports a 6x training-throughput gain over SLIME’s default setup.
How does SID-2 perform on benchmarks?
SID built a 506-question benchmark across 19 corpora. These include HotpotQA, Enron emails, SEC filings, PubMed and BrowseComp-Plus. All numbers below are self-reported from Tables 2 to 4 of the report.
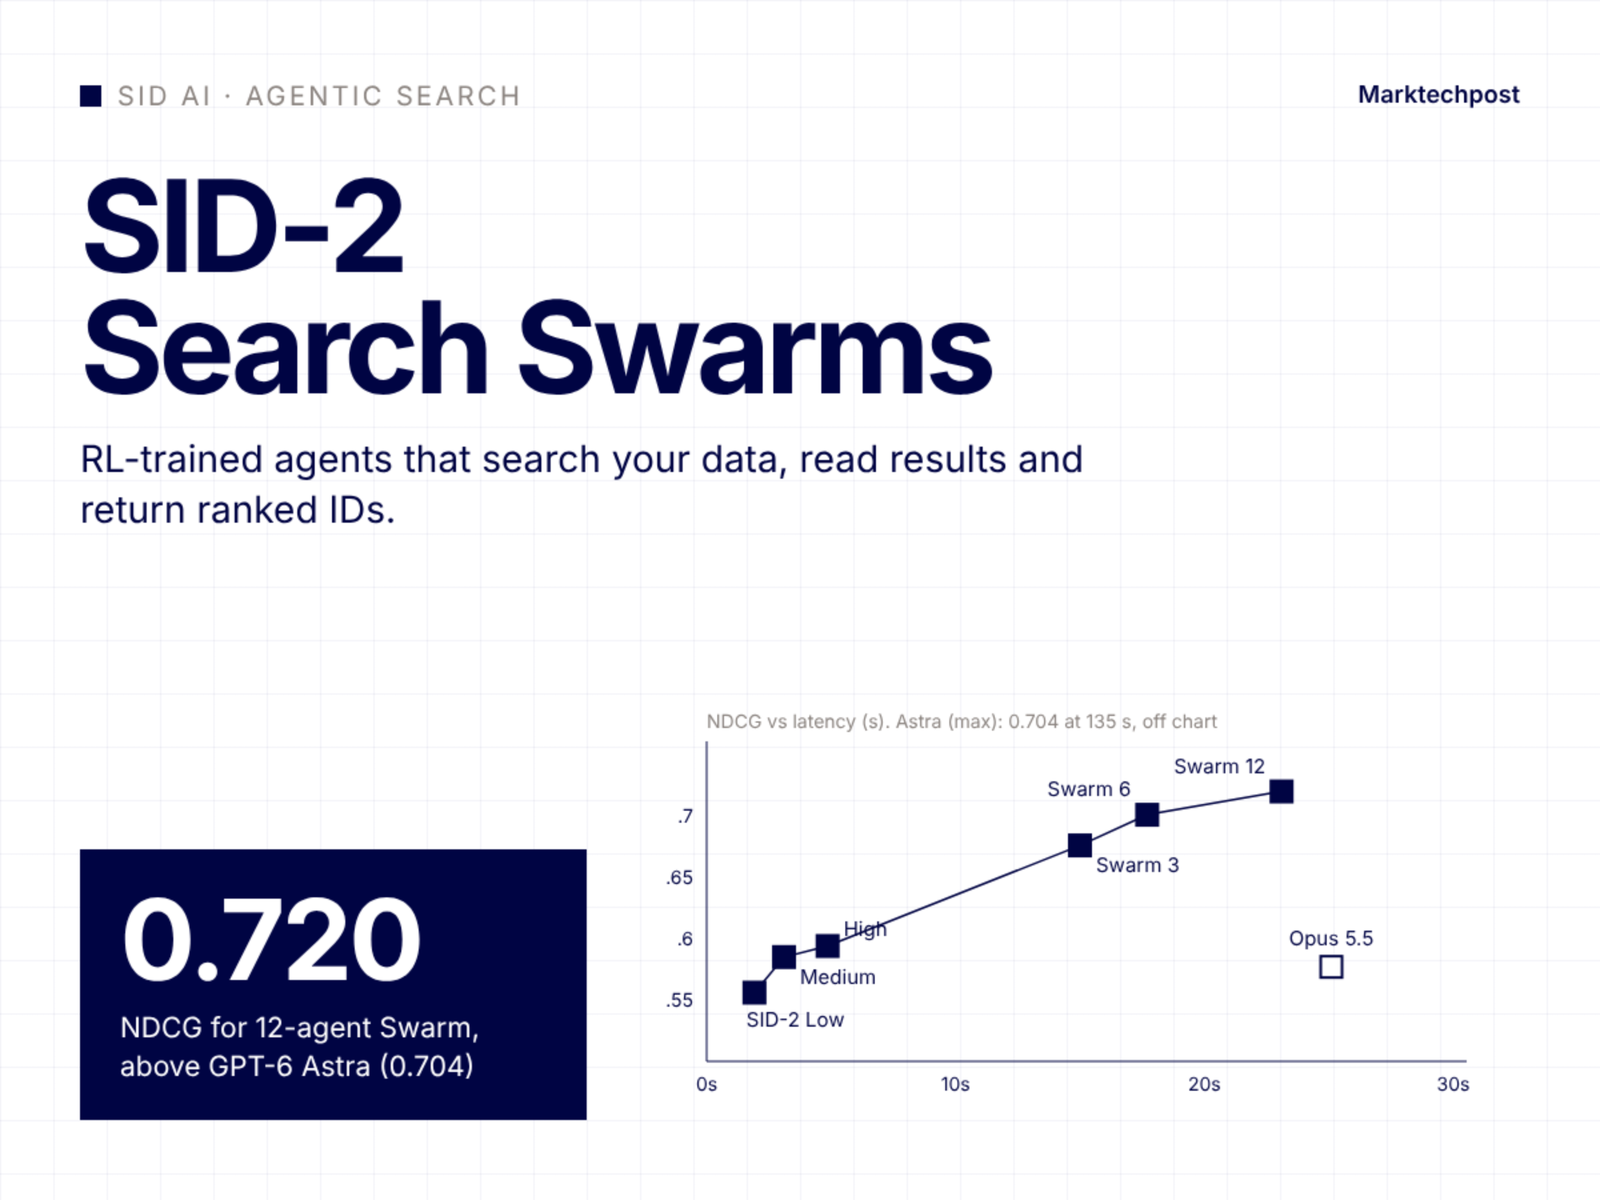
- SID-2 Medium: 0.585 NDCG in 3.11 s, versus Claude Opus 5.5 (medium) at 0.577 in 25.1 s.
- SID-2 Swarm, 6 agents: 0.701 NDCG in 17.7 s, versus GPT-6 Astra (max) at 0.704 in 135 s.
- SID-2 Swarm, 12 agents: 0.720 NDCG, the highest score in the table.
- Baselines: BM25 scores 0.260 and vector search plus reranker scores 0.287.
Swarm leads on 11 of 19 corpora. On WixQA, a single high-effort agent matches Astra at about 232x lower cost. At its lowest effort, SID-2 beats 4 parallel SID-1 runs with 13x fewer FLOPs.
SID-2 vs GPT-6 Astra vs Claude Opus 5.5
NDCG, time and cost rows are measured by SID on its own benchmark. Retrieval backend time is excluded.
How can developers deploy SID-2?
SID-2 is available through SID’s API and on Baseten. SDKs exist for Python (sid-sdk), TypeScript (@sid-ai/sid-sdk) and Go (github.com/sidhq/sid-go). A SageMaker helper covers AWS deployments. The reference implementation uses the OpenAI client format.
SID-2 costs $0.25 per million input tokens and $1.00 per million output tokens. Swarm costs $0.50 and $2.00. Cached input is 10% of the input price.
Key Takeaways
- SID-2 is an RL-trained agentic search model that returns ranked document IDs.
- SID-2 Medium matches Opus 5.5 retrieval at 0.585 NDCG in 3.11 s.
- 12-agent SID-2 Swarm leads SID’s benchmark at 0.720 NDCG.
- Pricing starts at $0.25 per million input tokens, with no reindexing.
- All results are self-reported; size and weights are undisclosed.
Check out the SID-2 technical report, the docs and the model page. You can check the deployment options and specs here through our GPULeaderboard.com chrome extension.
Also, feel free to follow us on Twitter and don’t forget to join our 150k+ML SubReddit and Subscribe to our Newsletter. Wait! are you on telegram? now you can join us on telegram as well.
Need to partner with us for promoting your GitHub Repo OR Hugging Face Page OR Product Release OR Webinar etc.? Connect with us
Michal Sutter is a data science professional with a Master of Science in Data Science from the University of Padova. With a solid foundation in statistical analysis, machine learning, and data engineering, Michal excels at transforming complex datasets into actionable insights.